Chinese developers are bypassing hardware limitations through algorithm design. Moonshot AI demonstrates that Mixture of Experts (MoE) dynamic routing and memory-efficient attention allow chinese ai models to match top-tier benchmark performances—including long-context reasoning—without access to cutting-edge AI accelerator chips.
- Hardware Barriers and Optimization Pressures on Modern Chinese AI Models
- MoE Architecture Is the Key to Solving Performance Challenges in Chinese AI Models
- How Moonshot Optimizes MoE for Ultra-Long Context Windows Beyond Hardware Limits
- Practical Lessons from Moonshot for the Chinese AI Model Development Community
- Frequently Asked Questions About Chinese AI Models
- Architectural Innovation Drives the Future of Chinese AI Models
By optimizing sparse expert routing and memory-efficient attention mechanisms, Moonshot successfully processes ultra-long context windows without relying on restricted high-end cluster hardware. This deep dive analyzes how sparse MoE scaling allows chinese ai models to maintain top-tier performance despite global hardware constraints.
Hardware Barriers and Optimization Pressures on Modern Chinese AI Models
High-End GPU Supply Crisis Impacting AI Infrastructure
The implementation of tight export controls on advanced semiconductors has created an unprecedented infrastructure bottleneck for organizations developing chinese ai models. Frontier artificial intelligence research historically relies on massively parallel compute clusters built from top-tier accelerators. When access to these unified memory architectures is constrained, engineers face severe hardware topology challenges that directly impact training schedules and model capacity limits.
Impact Level of Embargoes on Mathematical Compute and Memory Throughput
Hardware restrictions severely limit FP16 and INT8 tensor operations per second, effectively halving the raw FLOPs available per node. More critically, restricted hardware configurations come with reduced interconnect speed (inter-node bandwidth) and lower High Bandwidth Memory (HBM) capacity. When training chinese ai models, these hardware limitations manifest as severe memory bandwidth throttling. Mathematical calculations spend more time waiting for memory pages to swap than executing matrix multiplications, creating massive idle cycles across GPU cores.
The continuous evolution of sparse MoE architecture proves that algorithmic breakthroughs can overcome physical hardware barriers, empowering chinese ai models to redefine the boundaries of long-context intelligence on a global scale.
Luna
Escalating Infrastructure Operational Costs During Large-Parameter Scaling
Attempts to compensate for individual node performance deficits by clustering larger numbers of lower-tier GPUs exponentially inflate operational expenses. Power consumption scales non-linearly, heat dissipation requires expensive liquid-cooling upgrades, and physical space requirements expand dramatically. Furthermore, because inter-device communication links are slower, training chinese ai models on expanded clusters results in severe scaling inefficiencies, where adding 50% more nodes might yield less than 15% net compute gains due to synchronization overhead.
Read more: The Hidden Risk of AI Emergency Dispatch: When Faster Isn’t Better
Classic Challenges of Scaling Ultra-Long Context Windows in LLMs
Modern generative applications increasingly demand the ingestion of whole codebases, legal libraries, and lengthy technical manuals within a single prompt. For chinese ai models, processing context windows exceeding one million tokens presents a profound architectural challenge rooted in the foundational mathematics of the Transformer architecture.
Exponential Increase in Self-Attention Compute Costs as Token Count Soars
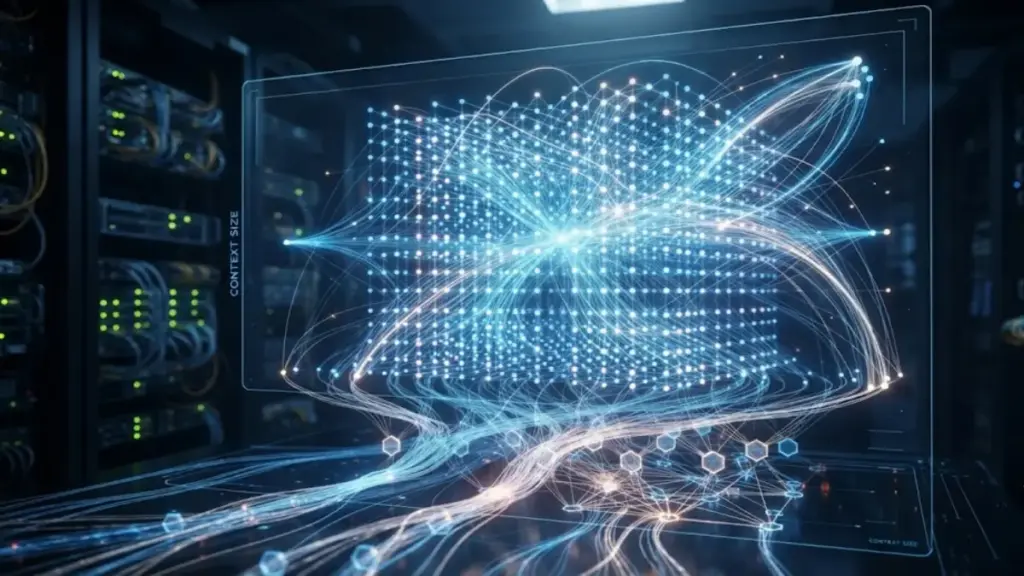
Standard multi-head self-attention mechanisms scale quadratically O(N^2) in time and space complexity relative to sequence length (N). When a model processes 100,000 tokens, the attention matrix requires calculation of 10 billion pairing interactions; at 1,000,000 tokens, this explodes to 1 trillion dynamic operations per layer. This mathematical dynamic rapidly depletes compute cycles on standard accelerator hardware, making native full-attention calculation practically unviable for long documents in chinese ai models.
VRAM Memory Spill Point and Latency Degradation at the Million-Token Scale
Beyond raw compute throughput, sequence scaling triggers an acute Key-Value (KV) cache memory crisis. Storing intermediate activations across dozens of transformer layers for millions of historical tokens requires gigabytes of active HBM per request. Once the physical memory limit of a GPU is breached, memory spillover forces system memory offloading over PCIe channels. This creates catastrophic response latency spikes, reducing inference throughput from dozens of tokens per second down to single digits for chinese ai models.
MoE Architecture Is the Key to Solving Performance Challenges in Chinese AI Models
Expert Decomposition Mechanism Reducing Per-Token Compute Overhead
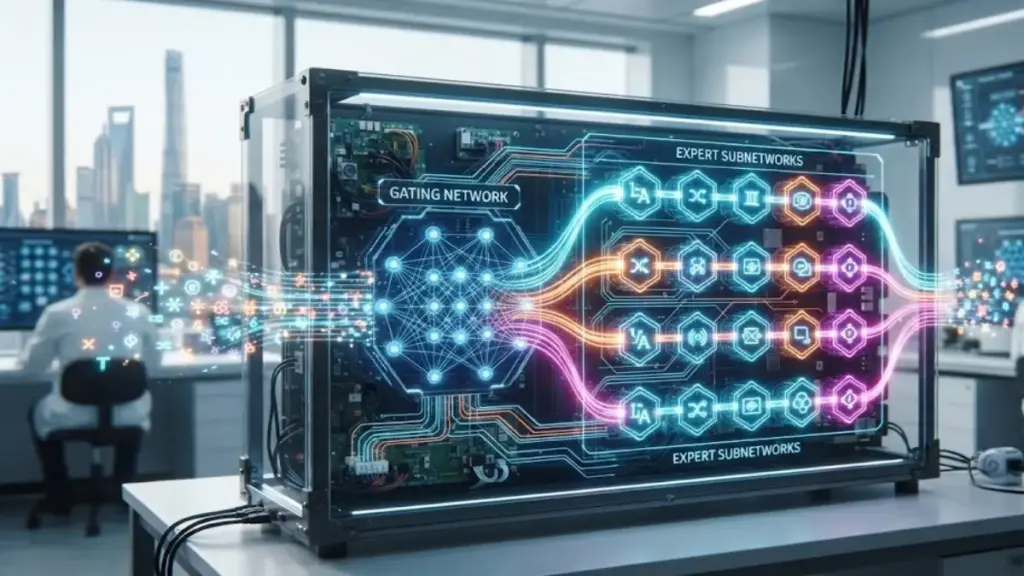
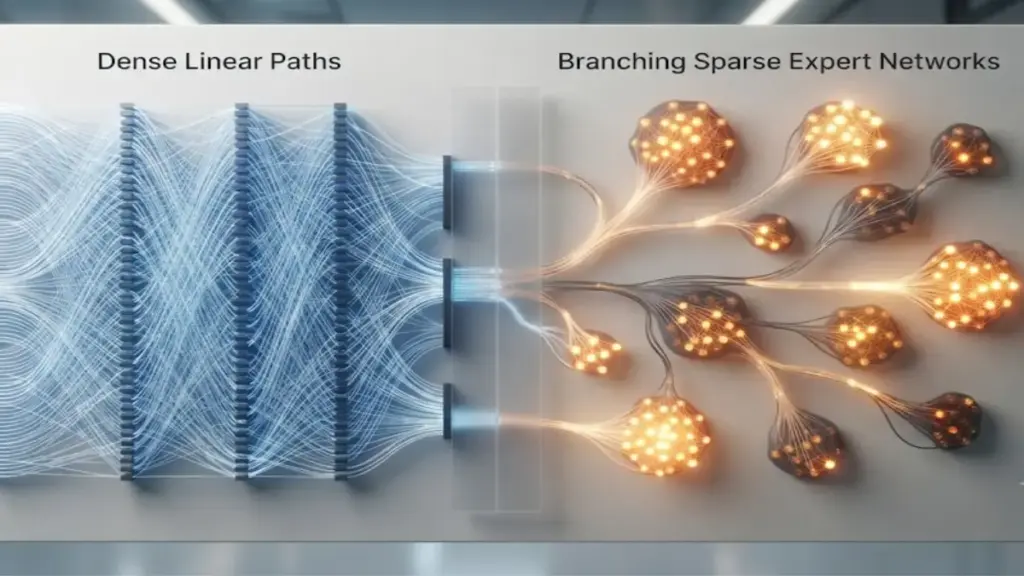
To bypass hardware-enforced limits, researchers building chinese ai models have fundamentally shifted away from dense architecture paradigms toward Sparse Mixture of Experts (MoE). In a traditional dense model, every single parameter processes every incoming token. MoE alters this dynamic by partitioning the feed-forward network (FFN) layers into multiple smaller, specialized sub-networks called “experts,” activating only a fraction of the total system per token.
Principles of Sparse Activation and Parameter Execution Optimization
Sparse activation allows chinese ai models to scale total parameter count—say, to 250 billion parameters—while maintaining the active compute cost of a 30-billion-parameter dense model. By engaging only top-k experts (typically 2 out of 8 or 16) for any given token, the model executes a fraction of its total mathematical operations. This decoupling of model capacity from inference latency allows high-parameter intelligence to run smoothly within restricted hardware budgets.
Intelligent Gating Network Systems for Precise Token-to-Expert Routing
The orchestrator of this process is the Gating (or Router) Network. This lightweight feed-forward layer calculates a probability distribution across available experts for each token. In leading chinese ai models, advanced gating mechanisms evaluate contextual semantics to route mathematical tokens to domain-specific experts (e.g., coding logic, linguistic nuances, or scientific formulas). The efficiency of the entire MoE system depends heavily on keeping this routing overhead negligible while avoiding routing hotspots.
Resource Efficiency Comparison: Traditional Dense vs. Next-Gen MoE Models
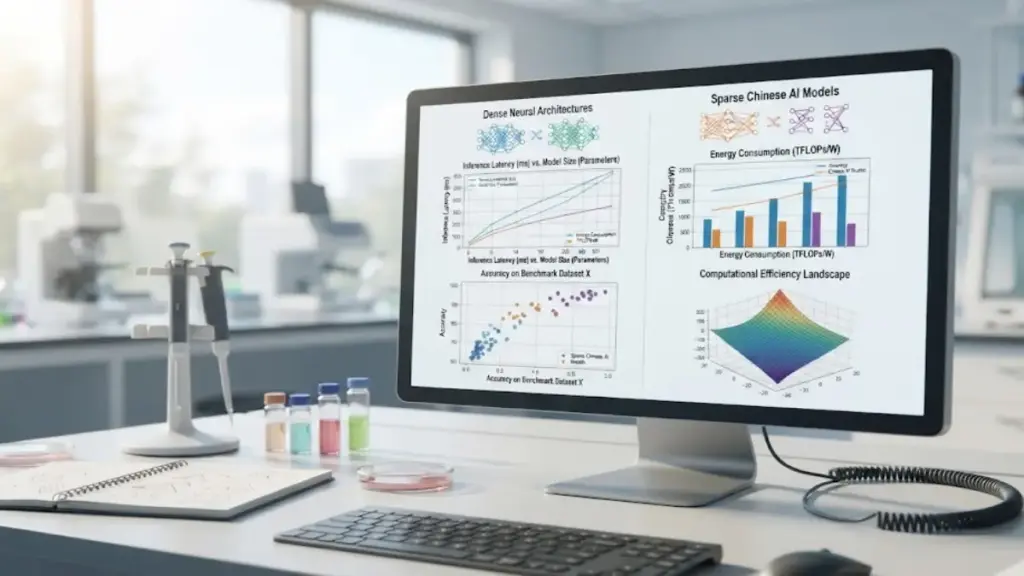
Evaluating model efficiency requires looking beyond raw parameter counts to analyze compute-to-intelligence ratios. Next-generation MoE structures change the unit economics of hosting and deploying high-capability LLMs.
Significant FLOPs Reduction Per Inference Step Despite High Total Parameter Counts
Because only a fraction of parameters are active per pass, FLOP requirements per generated token drop by 60% to 80% compared to dense equivalents of equal intelligence. Consequently, chinese ai models utilizing sparse architectures can achieve high reasoning throughput even when running on nodes with constrained floating-point operation caps, enabling enterprise-scale serving at a fraction of standard power consumption.
Maintaining Model Accuracy as Input Data Volumes Surge
Crucially, sparse activation does not compromise representation capacity. Because the total parameter count remains massive, the model retains vast memorized knowledge and nuanced reasoning pathways. When processing vast prompts, chinese ai models built on MoE retain accuracy markers comparable to top dense models like GPT-4, proving that compute sparsity need not degrade downstream task accuracy.
How Moonshot Optimizes MoE for Ultra-Long Context Windows Beyond Hardware Limits
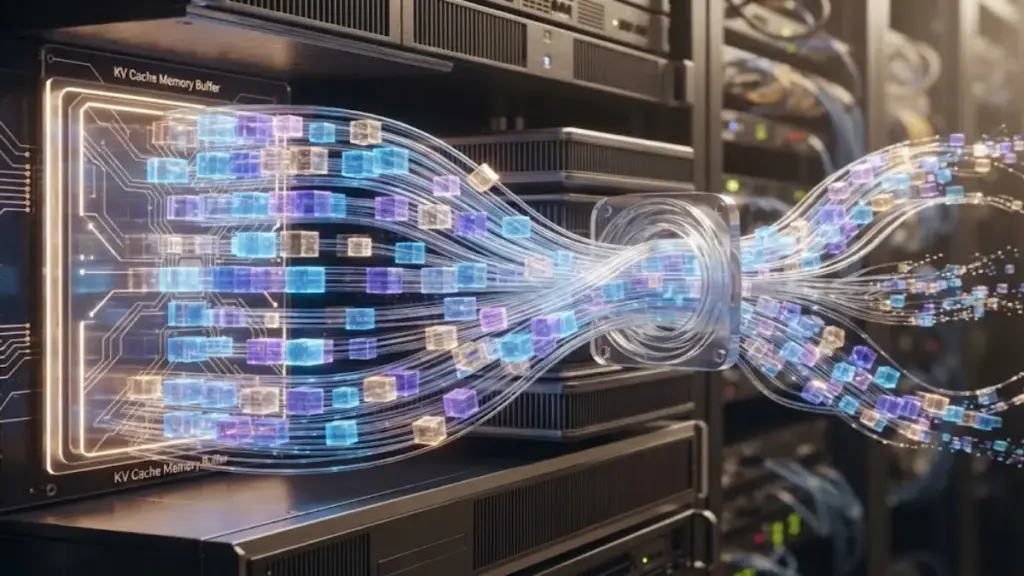
Breakthroughs in Memory Management Algorithms and Attention Buffer Allocation
Moonshot AI has pushed the boundaries of context scaling by modifying how attention states are managed in memory. Recognizing that HBM space is the ultimate bottleneck on embargoed platforms, Moonshot introduced proprietary memory management layers specifically engineered for chinese ai models.
More Read
KV Cache Compression Techniques and Context Data Restructuring
To keep multi-million token sequences within physical memory boundaries, Moonshot utilizes dynamic KV cache compression alongside Grouped-Query Attention (GQA). By quantizing historical key-value pairs into low-precision formats (such as INT4/FP8) without losing contextual precision, chinese ai models reduce the HBM memory footprint of long contexts by up to 75%. Data structures are continuously restructured in real time, dropping redundant attention states while preserving critical cross-document references.
Distributed Attention Computation Mechanisms Over Lower-Performance Chip Clusters
When single-node memory capacity is overwhelmed, Moonshot splits the self-attention calculation across interconnected cluster nodes using context parallelism. By breaking long prompt sequences into discrete chunks distributed across multiple GPUs, chinese ai models compute partial attention maps concurrently. Custom reduction algorithms then recombine these partial heads, allowing modest hardware pools to handle massive contexts seamlessly.
Read more: How Commercial VPNs Fast-Talk Audit Reports to Claim No-Logs Guarantees
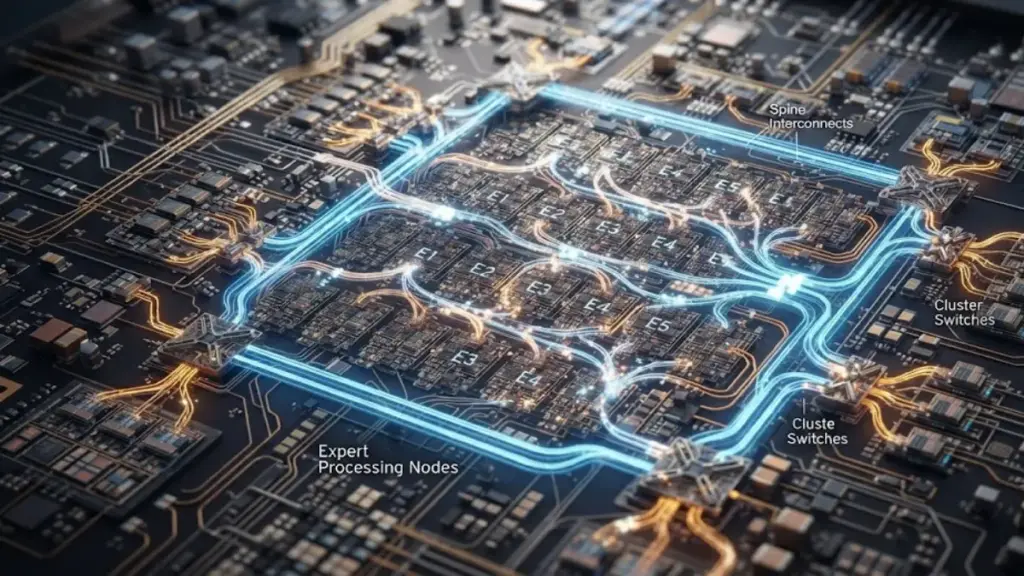
Expert Fragmentation and Inter-Node Bandwidth Optimization
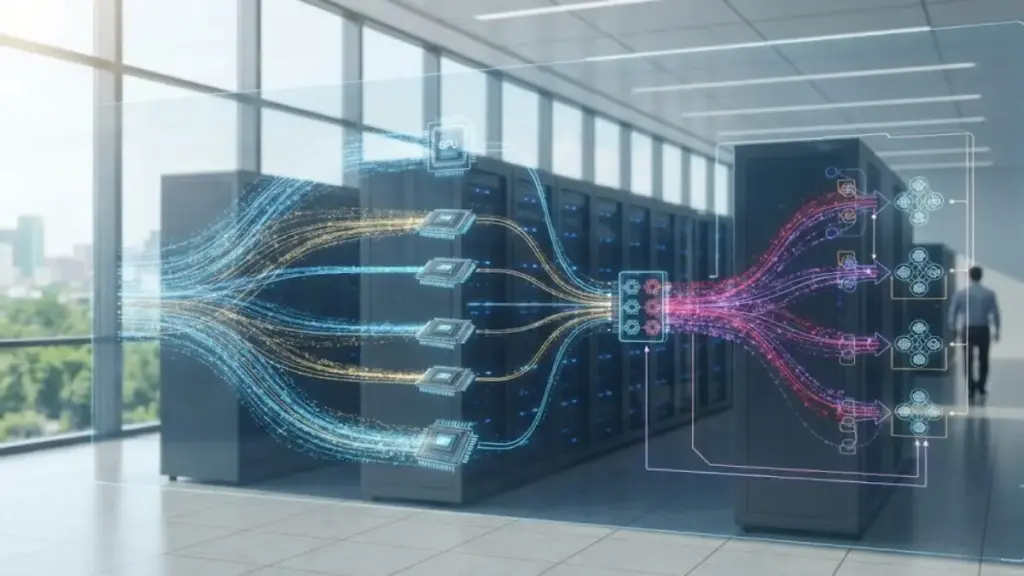
A critical vulnerability of distributed MoE systems is inter-GPU communication overhead. When tokens must jump between different physical chips to reach assigned experts, network bottlenecks can eliminate all sparse compute savings. Moonshot solved this for chinese ai models through advanced topology-aware routing.
Minimizing Communication Bottlenecks Between GPUs Using New Routing Algorithms
Moonshot implemented communication-aware routing algorithms that bias token distribution toward local experts whenever mathematically viable. By factoring physical interconnect topology into the Gating Network’s loss function, chinese ai models avoid unnecessary inter-node network hops over slow PCIe channels. Tokens cross physical server chassis only when specialized domain routing is strictly required.
Coordinating Data Parallelism and Expert Parallelism for Maximum Throughput
Achieving peak efficiency requires a carefully calibrated mixture of Data Parallelism (DP), Tensor Parallelism (TP), and Expert Parallelism (EP). Moonshot engineered a dynamic pipeline scheduler that automatically shifts workload partitioning based on sequence length and batch size. This balance enables chinese ai models to saturate available tensor cores without hitting memory wall deadlocks or idle communication stalls.
Practical Lessons from Moonshot for the Chinese AI Model Development Community
Strategic Shift from Hardware Brute Force to Algorithmic Optimization
Moonshot’s technical breakthroughs mark a broader paradigm shift in artificial intelligence engineering. When unlimited brute-force compute scaling is unavailable, software innovation becomes the decisive competitive advantage for creators of chinese ai models.
Importance of Designing Flexible Software Architecture Adapted to Existing Hardware
Rather than building models that demand non-existent hardware specs, developers are designing software architectures natively optimized for available silicon configurations. This hardware-software co-design paradigm allows chinese ai models to extract maximum utilization rates (MFU) from accessible GPU clusters, proving that software elegance can effectively offset hardware disparities.
Strategies for Building Low-Cost AI Models with Exceptional Commercial Performance
Cost-effective deployment is critical for commercial sustainability. By utilizing sparse MoE, developers cut inference serving costs significantly, enabling lower API prices for end users. Consequently, chinese ai models can offer ultra-long context capabilities commercially at a fraction of the operational cost typically associated with legacy dense foundation models.
Prospects for Equal Competition with Global Tech Giants
The success of Moonshot’s MoE implementation demonstrates that global technological parity remains achievable. Strategic algorithmic breakthroughs allow startups and open-source contributors working on chinese ai models to stay competitive on international benchmark leaderboards.
Closing the Technology Gap with OpenAI in Long Multimodal Data Processing
While leading global firms like OpenAI rely on vast compute infrastructures, architectural innovations in long-context attention allow chinese ai models to close the intelligence gap rapidly. Moonshot’s advances in processing text, code, and document streams spanning millions of tokens prove that smart routing algorithms offer a viable path to frontier-level AI performance.
Development Trends of Future Hybrid MoE Generations
Looking forward, the architecture of chinese ai models will continue to evolve toward Hybrid MoE structures—combining sparse expert routing with linear attention mechanisms, recurrent states, and dynamic layer dropping. These hybrid paradigms will further reduce hardware dependency, allowing future intelligence layers to run efficiently across diverse hardware environments.
Frequently Asked Questions About Chinese AI Models
How do MoE architectures help Chinese AI models bypass hardware chip embargoes?
MoE architectures allow chinese ai models to activate only a fraction of their total parameters per inference task. This drastically lowers the floating-point operations (FLOPs) and memory bandwidth required per token, allowing high-parameter systems to achieve competitive performance on lower-tier hardware clusters.
Can Chinese AI models maintain accuracy with ultra-long context windows?
Yes. By deploying advanced Key-Value (KV) cache compression, Grouped-Query Attention (GQA), and context parallelism, chinese ai models effectively process prompts exceeding one million tokens while maintaining high retrieval accuracy and logical consistency across extended sequences.
What is the main difference between Dense models and Sparse MoE models?
Dense models pass every token through all system parameters, creating massive compute overhead. Sparse MoE models route tokens dynamically to specific sub-networks (experts), ensuring that chinese ai models consume compute resources proportional to active parameters rather than total parameters.
Architectural Innovation Drives the Future of Chinese AI Models
The remarkable achievements of Moonshot AI highlight a fundamental truth in frontier artificial intelligence research: physical hardware constraints can be effectively mitigated through algorithmic innovation. By pioneering memory-efficient context handling and sparse expert routing, Moonshot has proven that chinese ai models can deliver top-tier performance without relying on restricted accelerator clusters.
As Mixture of Experts architectures continue to evolve into more sophisticated hybrid paradigms, the global AI landscape will increasingly be shaped by software efficiency, architectural ingenuity, and intelligent resource allocation.
PLEASE LEAVE A COMMENT TO SHARE YOUR FAVORITE THOUGHTS OR FOLLOW OUR BLOG FOR THE LATEST UPDATES.